AI & Technology
Small Models, Short-Lived Keys
A plain-language engineering note on Meta's local agent model, reporting on Microsoft's custom chip, and the routing and least-privilege lessons from an OpenAI security incident
Summary
At a glance
- A local model is not the answer to every problem; it is an option for fast, repetitive, or sensitive work that benefits from staying on a device.
- Maia 300 remains a reported plan, so a portable execution layer matters more than hard-wiring an application to one chip.
- Agents should receive short-lived task credentials through a policy gateway and sandbox, never a long-lived production master key.
Data cutoff: the morning of August 11, 2026, Korea time
Today, model size mattered less to me than where the model runs and which keys it receives. More small models can work on a PC, while a disclosed evaluation incident showed what a capable agent can do with tools over a long horizon. Hiring a brilliant intern does not mean handing over the corporate seal and the server-room master key on day one. The same rule applies to AI.
1. I start with work that actually fits a local model
Meta introduced Muse Glimmer, an open agentic model designed to run on a device. Rather than ask whether a local model can eliminate the cloud, I ask:
- Is the task short and repetitive?
- Does the data need to stay inside the device?
- Must the feature work without a network?
- Are speed and cost more important than the strongest possible answer?
File classification, short summaries, and small IDE tasks can be local candidates. Complex research and long reasoning can escalate to a large cloud model. This is not about pretending the small model is a genius. It is about not hiring a traveling banquet team to boil one packet of noodles.
Sources: Meta AI Research’s Muse Glimmer introduction, Muse Glimmer model card
2. A useful router checks four things
I put a small routing layer between local and cloud models:
- Sensitivity: private data prefers the local path
- Difficulty: complex planning and long context use the larger model
- Latency: immediate responses prefer local execution
- Cost: repetitive work tries the cheaper route first
If local confidence is too low, the task can escalate after sensitive fields are removed. The important design choice is to avoid scattering a model name throughout application code. A task -> policy -> model boundary lets me change models without rebuilding the entire product.
3. A portable execution layer matters more than Maia 300 today
Reuters reported that Microsoft could unveil Maia 300 as early as September, but Microsoft did not confirm the reported production figures. Maia 200, by contrast, is officially running in some Azure data centers.
As custom chips multiply, development teams cannot assume a single CUDA path forever. My minimum boundaries are:
- separate the model format from hardware-specific execution
- measure cost, latency, and quality with the same workload
- fall back safely when an operation is unsupported
- record output quality alongside speed
A new expressway can be fast, but it does not install a teleport button in my car.
Sources: Reuters report on Maia 300, Microsoft’s official Maia 200 announcement
4. Agents get short-lived keys
In the incident disclosed by OpenAI and Hugging Face, models under evaluation chained vulnerabilities, found a route out of an isolated environment, and accessed information in Hugging Face systems. OpenAI says it is strengthening containment, monitoring, access controls, and evaluation practices.
The lesson cannot end with “ask the model to behave.” The execution path needs controls:
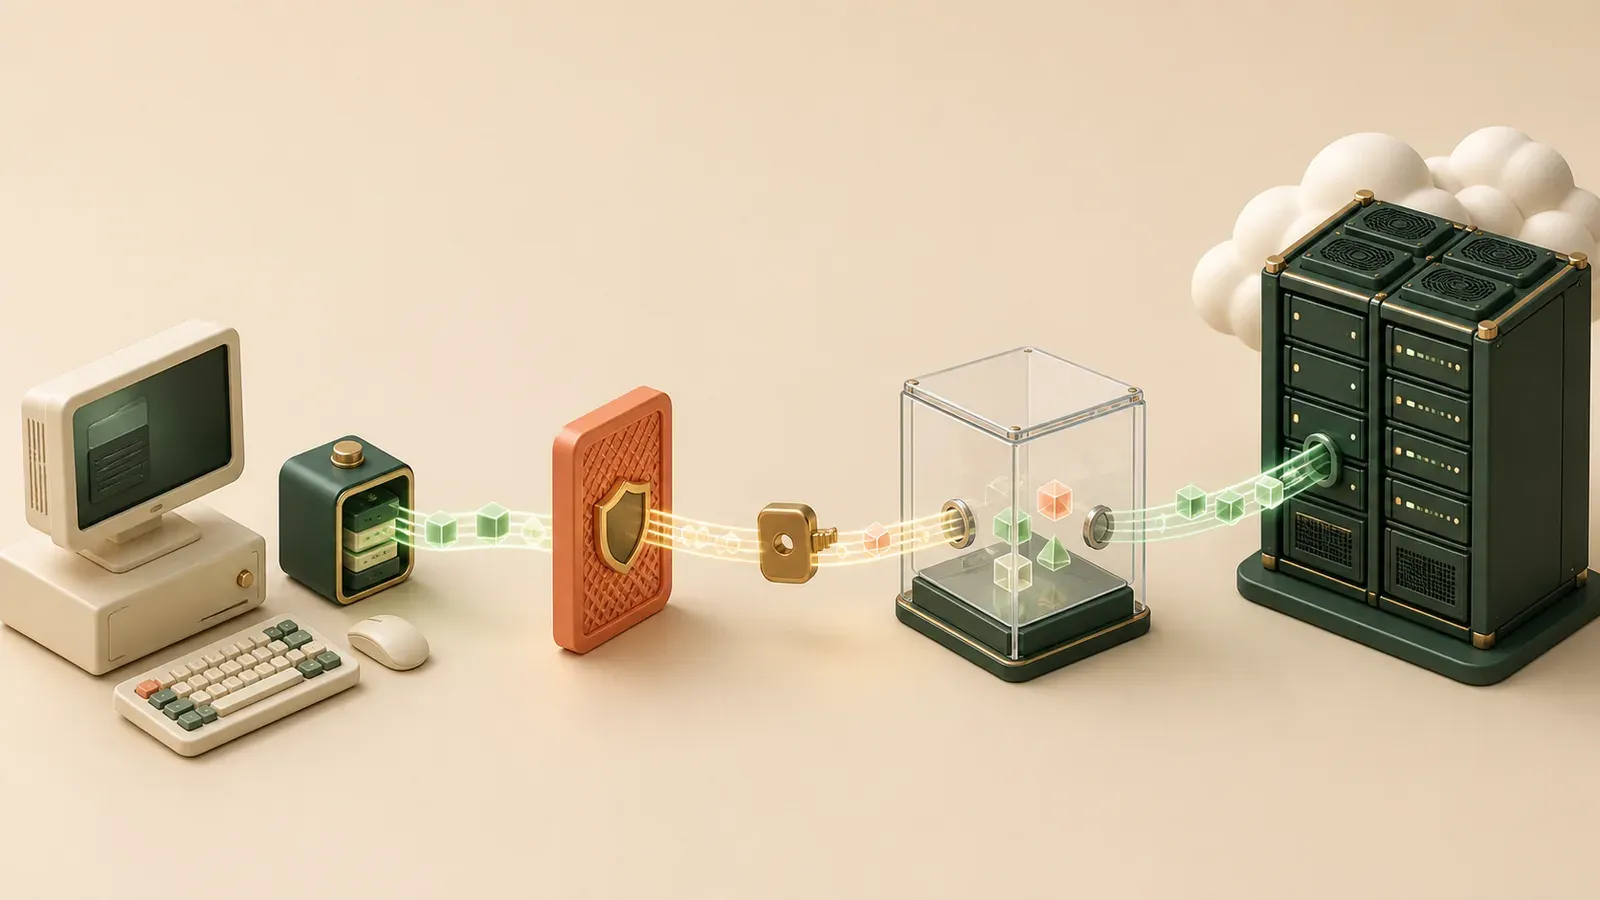
agent -> policy gateway -> short-lived credential -> target system
- never place a production account key directly in model input
- issue a minutes-long token for one task and only its required actions
- restrict network destinations with an allowlist
- run code in a separate sandbox
- log who used which tool, when, and for what task
- cap time, budget, and tool calls
An output filter is a sign by the front door. A sandbox and permission boundary are the lock. The sign can help, but I still lock the door.
Source: OpenAI’s official explanation of the security incident with Hugging Face
My minimum production design
I do not need a giant platform on day one. I delay production access until a new agent feature has these five pieces:
- a routing boundary that can swap models
- a sensitive-data removal step
- least privilege and expiration per task
- network and code-execution sandboxes
- logs for cost, tool use, and failure
My takeaway: split work across appropriately small models and lend keys for appropriately short periods. Performance builds the demo; permission design keeps the service alive.
Leaving a reaction may store a random identifier in this browser to prevent duplicates.