AI & Technology
Logs Needed an Attendance Check
A plain-language AI technology note on using Google SecOps ingestion activity to separate missing, delayed, and failed logs and build an operational checklist
Summary
At a glance
- No alert is not the same as healthy security-log ingestion, so teams need separate observability for the collection pipeline.
- Google SecOps can expose missing, delayed, and failed activity for push and pull Feeds and narrow investigations by Feed or Collector.
- My baseline metrics are heartbeat, last successful receipt, latency, failures, retries, and source-to-ingestion volume.
Source baseline: official Google Cloud documentation, last updated July 26, 2026
For a while, I treated a security dashboard with no alerts as a quiet day. The problem is that a dashboard can stay remarkably calm when its log collector stops. That is like reporting a peaceful meeting from an office where nobody showed up.
Google’s recent SecOps documentation is a useful example of closing that gap. The important idea sits before the AI detection model: the collection process needs its own status trail.
1. Split the path into parts
A security event travels roughly along this path:
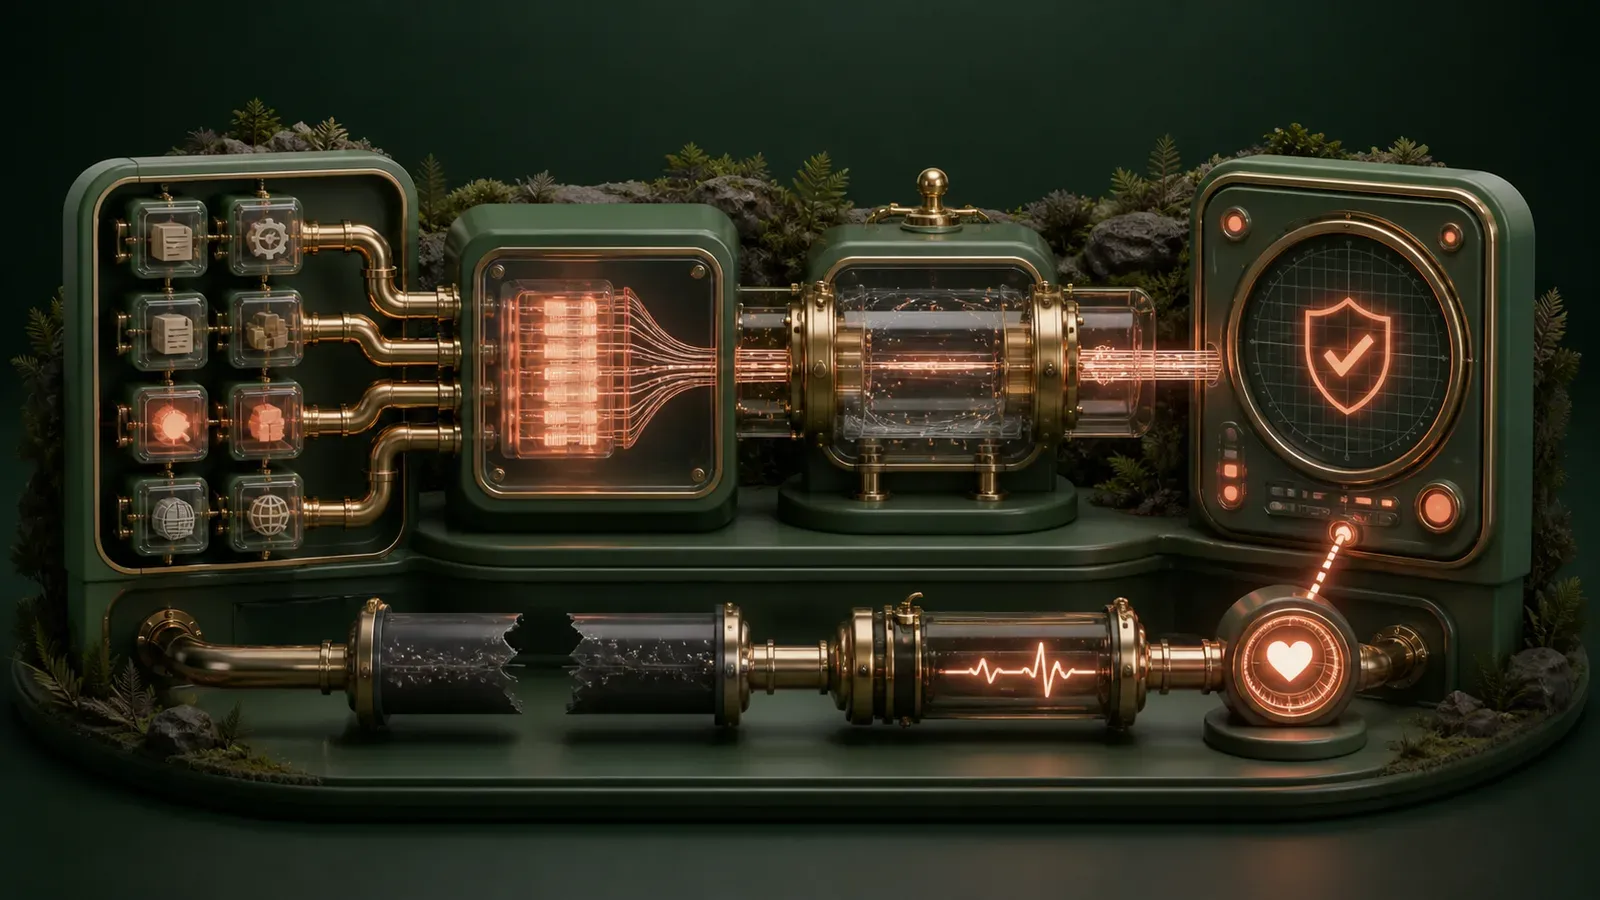
source system → Collector or Feed → ingestion pipeline → SIEM storage → detection rule
“Zero results” at the end has several possible causes:
- Nothing suspicious happened.
- The source failed to create a log.
- The Collector stopped.
- Delivery was delayed or failed.
- The SIEM received the event, but the rule missed it.
Without visibility into the front of that chain, I cannot distinguish peace from a broken pipe.
2. What Google SecOps exposes
The Public Preview feature sends SecOps ingestion and Feed activity logs into Cloud Logging. Google says it covers both push and pull mechanisms and helps teams investigate missing, delayed, and failed logs.
Investigators can narrow the view with feed_id or collector_id. Debug with logs opens Logs Explorer with a Feed-specific filter already applied. Gemini Cloud Assist can also analyze the same log and metric telemetry.
AI is the assistant here, not the plumber. If the network permission or ingestion configuration is wrong, an elegant explanation can improve the incident report while leaving the pipe blocked.
Sources: Google Cloud documentation for analyzing SecOps ingestion activity, Google SecOps release notes
3. The metrics I want by default
The same principle applies to ordinary application logs. I want these five signals outside the event stream itself:
- Heartbeat: a periodic “collector is alive” signal
- Last successful receipt: the point at which the gap began
- Delivery latency: event time versus arrival time
- Failure and retry counts: evidence of quiet loss
- Source-to-ingestion volume: a drop from the normal baseline
I also separate security alerts from pipeline-health alerts. A smoke alarm and its low-battery warning solve different problems. Ignore the battery warning, and the next alert may arrive as a neighbor pounding on the door.
4. The Public Preview boundary
This is Pre-GA functionality. I do not assume it has the same stability as a generally available feature. Before using it in production, I would record:
- supported scope and known limitations;
- retention period and logging cost;
- how Feed and Collector identifiers are managed;
- a fallback query path if the preview changes;
- the difference between Gemini’s suggestion and a human-applied action.
Enabling a new feature matters less than knowing how to investigate when that feature changes.
My conclusion
The absence of logs is itself a state worth observing. No model can reason well after its input disappears. Before I ask about detection accuracy, I now ask, “Did all the logs come to work today?” I did not expect attendance to become a security strategy, but operations often survives on ordinary questions.
Leaving a reaction may store a random identifier in this browser to prevent duplicates.