AI & Technology
Give the Agent a Dashboard
An approachable engineering guide to completion rate, latency, cost, recovery, runtime abstraction, license checks, and guarded agent payments.
Summary
At a glance
- Split speed into TTFT, output rate, p95 latency, and end-to-end task time.
- Put agent harnesses behind a common runtime interface while testing their permission and feature differences.
- Add merge policies, spend limits, idempotency, and receipts to dependencies and autonomous payments.
Source cutoff: the morning of August 14, 2026, Korea time
AI announcements love a top-speed number. My production service needs a wider dashboard. I want to know how quickly the first token appeared, whether the job actually finished, whether failure was recoverable, and whether the bill was already waiting in my chair.
A taxi going 300 km/h is not useful if it passes the destination. It merely makes the fare grow faster. Here is the dashboard I would give an agent.
1. Split “fast” into four measurements
OpenAI’s Fast mode documentation says GPT-5.6 Sol can receive faster, more consistent processing, but a sudden traffic ramp can move requests back to Standard. A single average hides that behavior.
I measure at least four things:
- TTFT: time from request to first token
- Output rate: output tokens generated per second
- p95 latency: how long the slowest 5% of requests took
- End-to-end task time: time through tool calls and retries
I attach the returned service_tier and error rate. If I requested the fast route but received Standard processing, the performance report should say so. Starting a stopwatch and ignoring the finish line would get me scolded even at a school sports day.
Source: OpenAI API Fast mode
2. Separate the model from the agent runtime
Vercel’s HarnessAgent puts Claude Code, Codex, Pi, and other harnesses behind a common interface. AI SDK 7 expands that runtime layer. My architecture is simple:
business feature → AgentRuntime → actual agent → model and tools
The business feature requests “inspect this repository and prepare a safe fix.” AgentRuntime handles sessions, streaming, cancellation, permission approval, and sandbox cleanup. Configuration selects the implementation.
I still test every runtime’s differences:
- Tool calling and structured-output support
- Session resume and cancellation behavior
- File, network, and shell permissions
- Logging and cost visibility
- Cleanup and retry behavior after failure
A universal remote does not add a “cook rice” button to every appliance. Abstraction is not about pretending differences do not exist; it is about managing them in one place.
Sources: Vercel HarnessAgent, Vercel AI SDK 7
3. Completion is more than opening a pull request
If I score only response success, a confidently wrong answer passes. I define completion before the test:
- It changed only the requested files.
- Tests and static checks passed.
- It did not introduce unrelated edits.
- It left evidence a reviewer can understand.
- It preserved the original state when it failed.
A model that edits in 20 seconds and needs two rollbacks can cost more than one that finishes correctly in 40 seconds. I therefore track cost per completed task, not just price per token.
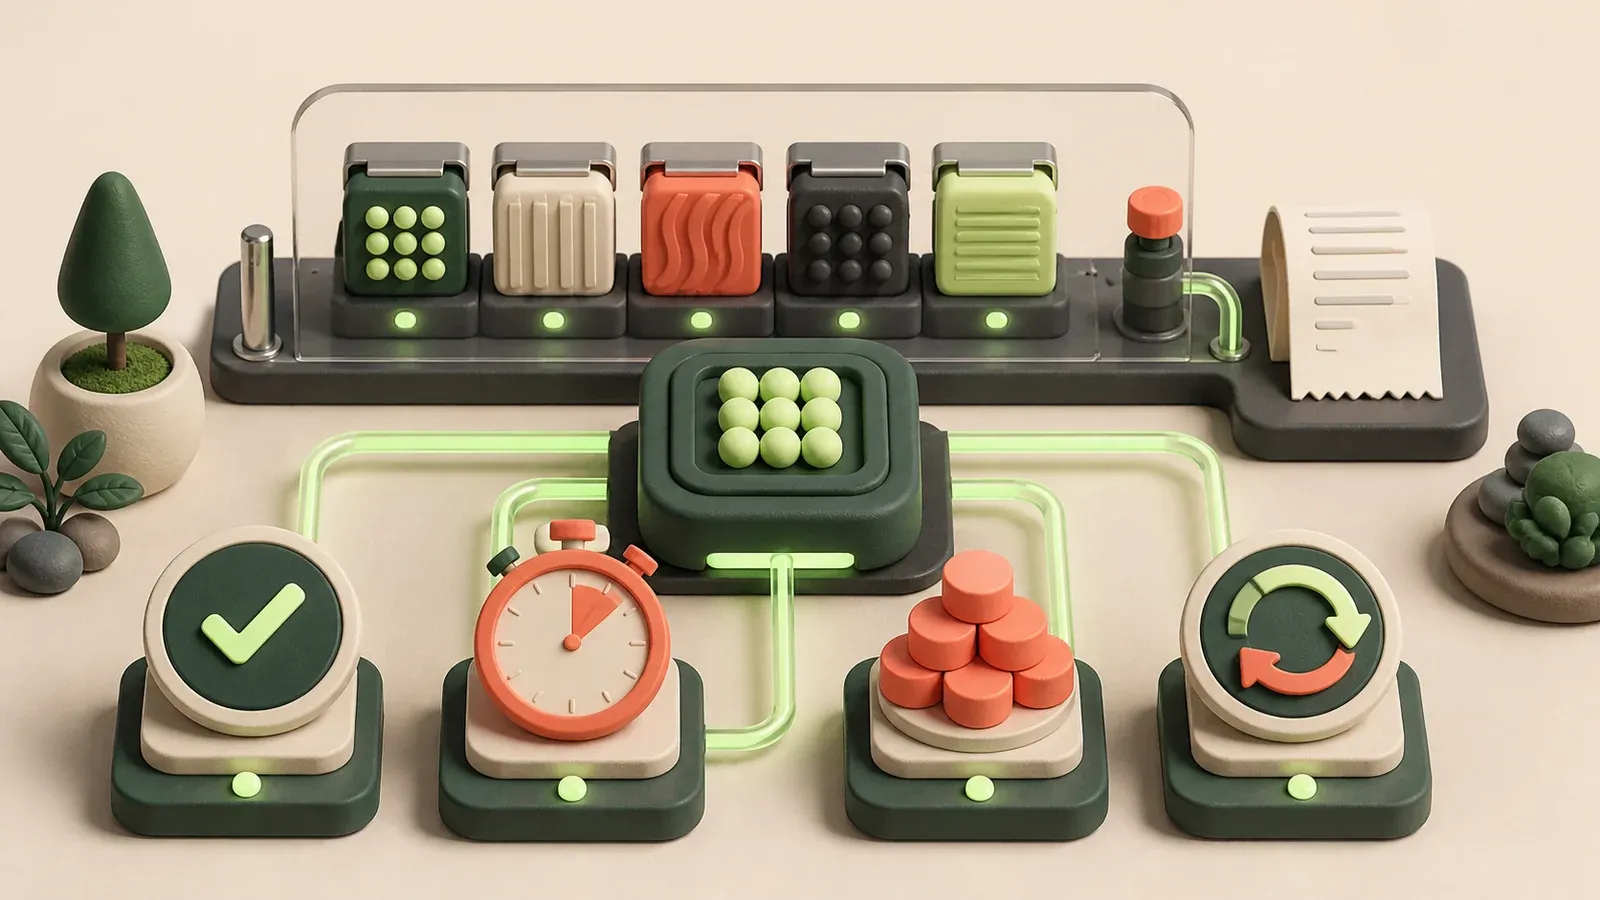
My central dashboard has four cells:
completion rate | total task time | cost per completion | recovery rate
A benchmark resembles an interview score. I still need to see whether the new hire freezes beside the office printer.
4. Inspect AI-selected packages at the door
GitHub’s license-compliance public preview lets an enterprise define central rules and stop a noncompliant dependency before merge. Faster code generation also means faster package intake, so this gate matters more.
My CI order is:
- Generate an SBOM from the lockfile.
- Detect new dependencies and version changes.
- Apply license allow-and-deny rules.
- Scan for vulnerabilities and malicious packages.
- Record the approver and expiration date for exceptions.
“The AI recommended it” is not a license. Autocomplete does not stamp the signature box on a contract.
Source: GitHub open-source license compliance public preview
5. Start an agent wallet with an allowance envelope
Circle Agent Stack and the Nanopayments testnet let developers experiment with agents paying for APIs and services over x402. Technical possibility is not operational safety.
I put a policy layer in front of payment:
agent → purchase request → policy check → limited wallet → payment → receipt
The policy needs at least:
- Per-call, hourly, and daily spend limits
- Approved sellers and assets
- An idempotency key to prevent duplicate payment
- A link between purchase purpose and delivered result
- Cancellation, dispute, and failure rules
- A human-approval threshold
Giving an agent an unlimited wallet is like asking it to check the fridge and handing over both the house key and corporate card. Intelligence and thrift are not the same option.
Sources: Circle Agent Stack, Circle Nanopayments testnet
The operating baseline I will use
When I add a new model or agent, I will:
- Fix completion criteria across 20–50 real tasks.
- Compare Standard and faster processing with identical inputs.
- Record p50, p95, and cost per completed task.
- Document permission, session, and recovery differences by runtime.
- Put dependency and payment actions behind separate policy gates.
- Deliberately inject failures and verify recovery.
My conclusion is simple: give the agent a dashboard before a turbo button. A fast demo earns applause. A system that exposes speed, cost, permissions, and recovery protects Monday morning.
Leaving a reaction may store a random identifier in this browser to prevent duplicates.